Small services often accumulate recovery logic before their normal path is fully understood. Every retry, alternate endpoint, and compatibility branch adds another state that must be observed and tested.
Make the common path boring
A useful default is explicit, easy to inspect, and safe to repeat. For a static site, that can be as simple as:
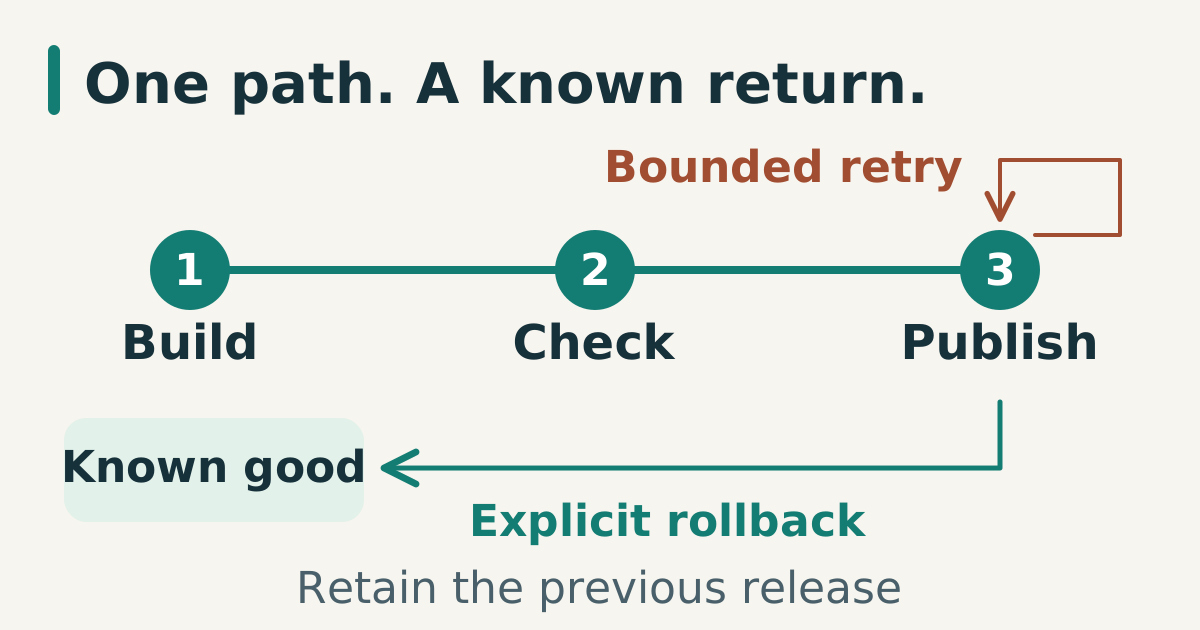
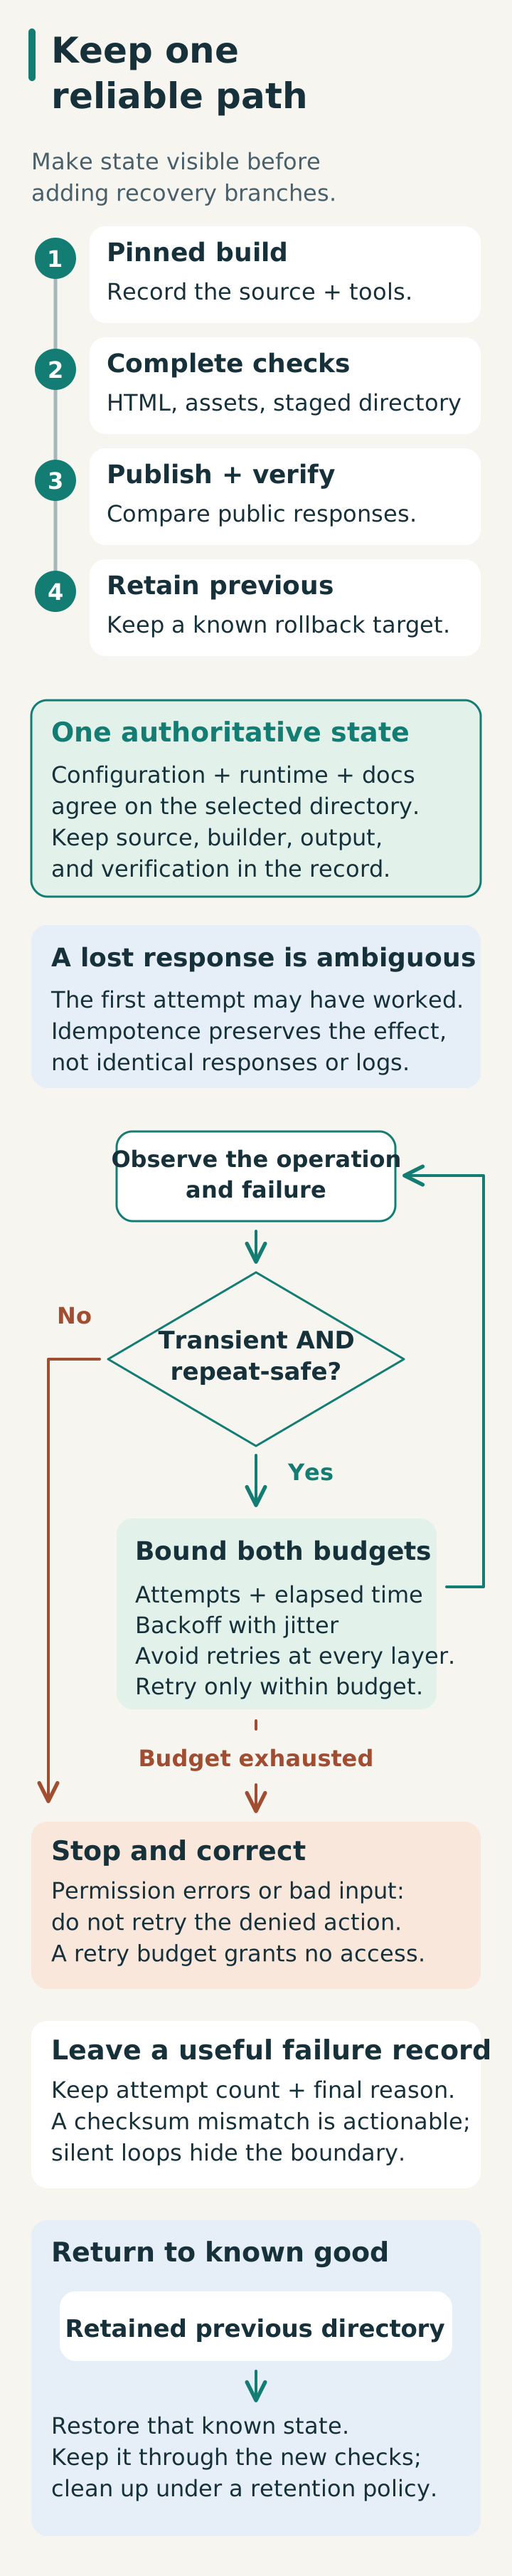
- Build from a pinned toolchain.
- Check the generated HTML, assets, and complete staged directory.
- Publish that directory, then verify public responses against it.
- Keep the previous directory available for rollback.
The sequence is less impressive than a multi-stage deployment system, but its state is visible. When something fails, the operator can answer whether the problem is in the source, the build, the copy, or the web server.
Retry only a bounded operation
Retries are useful when the failure may be transient and repeating the operation preserves its intended effect. Idempotence does not mean every response or incidental log entry is identical; after a lost response, the first attempt may already have succeeded. A download from an origin may be safe to retry; a database migration may not be. Treating every error as retryable hides the boundary that needs attention.
When a retry is appropriate, record the attempt count and the final reason. A log entry such as “publish failed: checksum mismatch” is more actionable than a sequence of silent retries followed by a generic timeout.
Prefer one authoritative state
Configuration, runtime state, and documentation should agree about which directory is live and which command produces it. If a release can be copied to three different paths depending on who runs it, recovery becomes guesswork.
For a static deployment, a short release record is enough:
release: 2026-07-20
source: git commit <commit-id>
builder: Hugo 0.165.0
output: public/
verification: links + headers + checksums
The placeholder commit ID is deliberately resolved at release time instead of being invented in documentation.
Recovery should restore a known state
Recovery is easiest when it returns the service to the last known-good directory, not when it chooses among several partially built alternatives. Keep the previous output until the new output has passed its checks, then remove old copies according to a retention policy.
The goal is not to eliminate failure. It is to make the failure small enough to explain and the recovery small enough to trust.
Bound retries by both attempts and elapsed time. Use backoff with jitter when many clients could retry together, and avoid stacking retries at every layer. Permission errors and deterministic bad input need correction, not a longer retry loop.
Sources
- RFC 9110 — HTTP Semantics, section 9.2.2 on idempotent methods and retries, checked 2026-07-20.
- Static-site release checklist, local companion resource.
- AWS Builders’ Library: Timeouts, retries, and backoff with jitter, retry amplification, bounded retry budgets, backoff, and jitter, checked 2026-10-15.