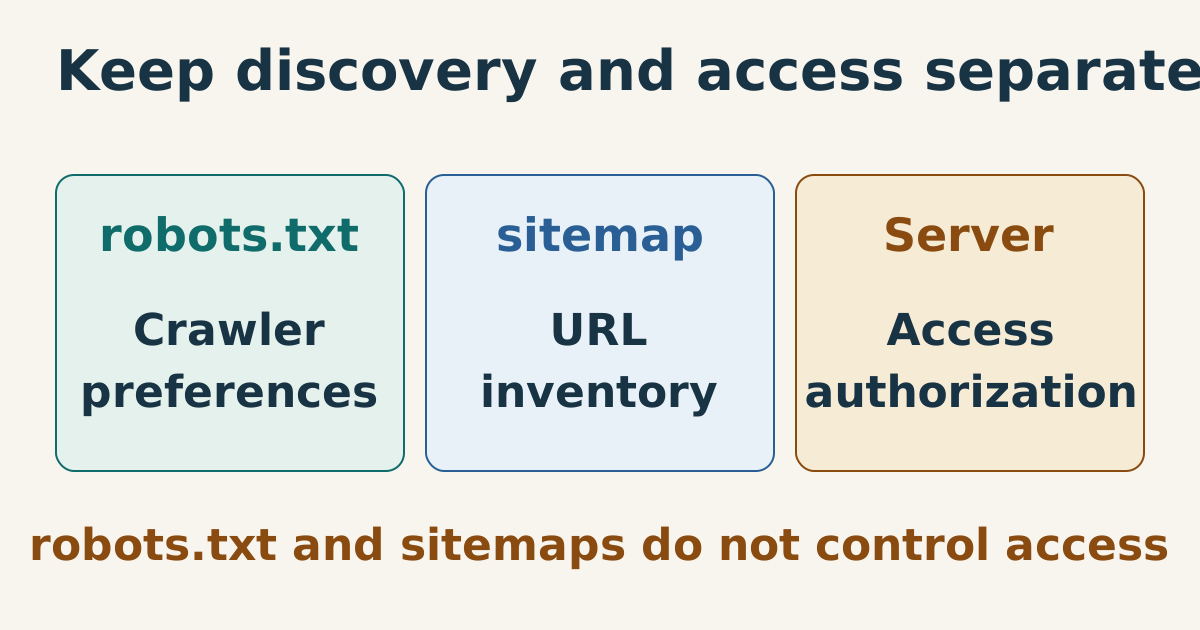
Two small files are often treated as if they were a security boundary. They are not. A robots.txt file describes crawler preferences, while a sitemap gives search systems a list of URLs that belong to the site.
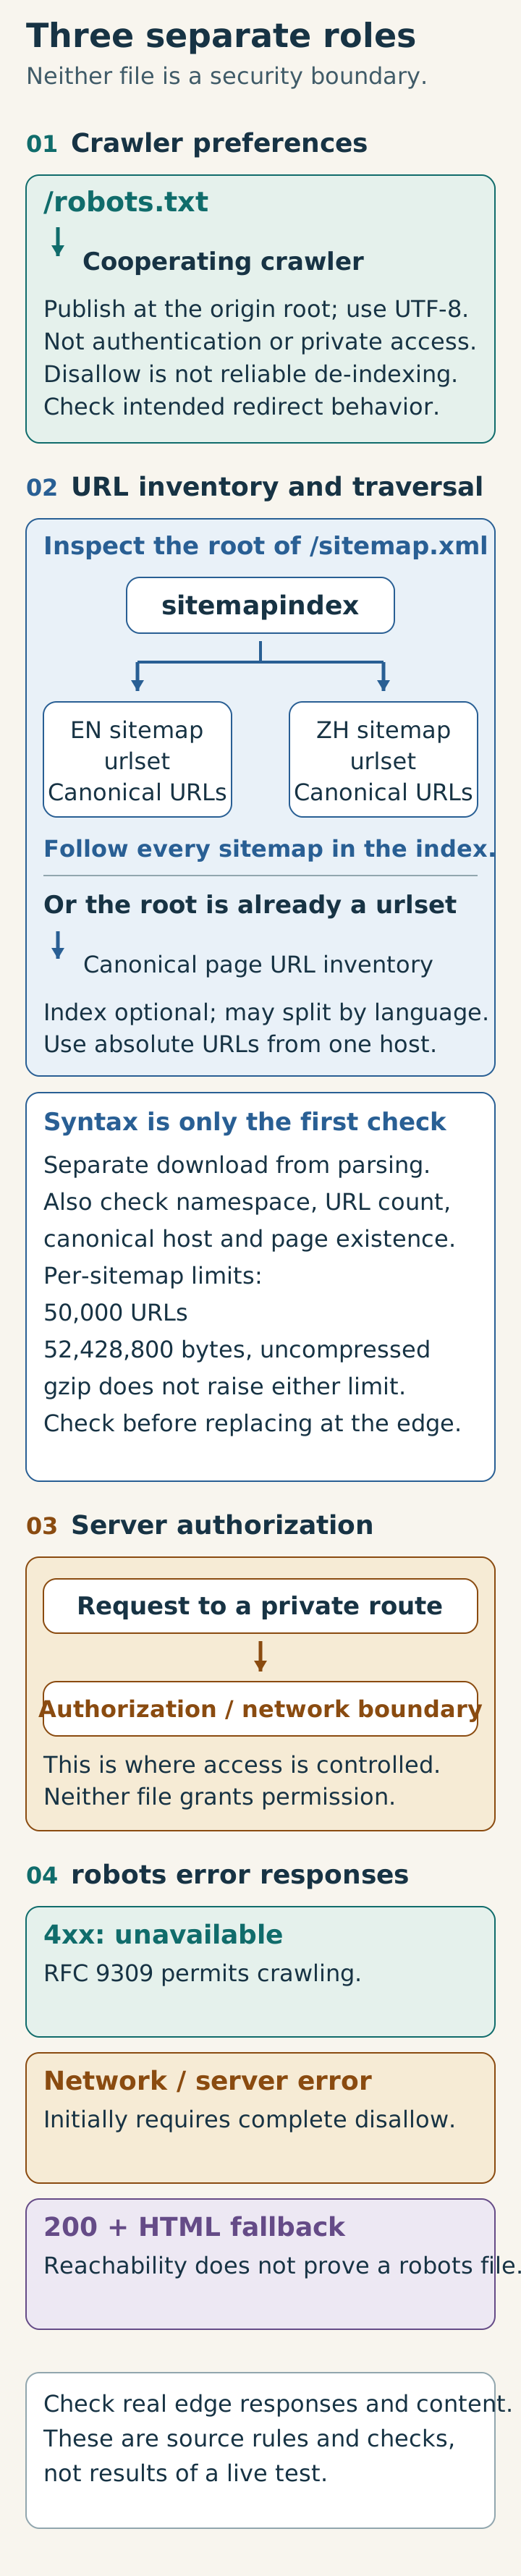
What robots.txt can and cannot do
The rules are published at the origin’s /robots.txt path and are read by cooperating crawlers. They do not protect a private directory, remove a URL from the network, or replace authentication. A route that must not be public needs server authorization or a network boundary.
Keep the file boring and test its actual location:
User-agent: *
Disallow:
Sitemap: https://www.example.test/sitemap.xml
The file should be UTF-8. If a deployment redirects it, verify the crawler behavior you intend rather than assuming every client follows the same chain.
What a sitemap adds
A sitemap is an inventory, not a permission list. Use absolute URLs from one host, encode XML values correctly, and include only canonical pages that you are prepared to publish. Do not list a URL merely because it exists in a build directory.
Each sitemap may contain at most 50,000 URLs and 50 MB (52,428,800 bytes) uncompressed; gzip does not raise that limit. An index is optional for a small site, but multilingual generators may legitimately produce one pointing to separate language sitemaps. Inspect the root element and follow each listed sitemap rather than assuming /sitemap.xml is a URL set. Validate it as XML and request it through the same HTTPS edge as a normal page.
curl -fsS https://www.example.test/robots.txt
curl -fsS -o sitemap.xml https://www.example.test/sitemap.xml && \
  xmllint --noout sitemap.xml
Separate download and parsing so a failed fetch cannot be hidden by a successful parser. Well-formed XML is only a syntax check: also validate the namespace, URL count, canonical hosts, and whether listed pages exist. If xmllint is not installed, parse the XML in the same CI environment that publishes it. The important part is that the check runs before the file is replaced at the edge.
A robots Disallow is not a reliable de-indexing instruction. Also test error responses: RFC 9309 permits crawling when robots is unavailable with a 4xx response, while a network/server error initially requires complete disallow. Accidentally serving the HTML fallback with status 200 can therefore change crawler behavior even though the URL appears reachable.
Sources
- RFC 9309 — Robots Exclusion Protocol, robots rules, file location, and user-agent matching, checked 2026-07-21.
- Sitemaps Protocol, sitemap XML structure and discovery, checked 2026-07-21.