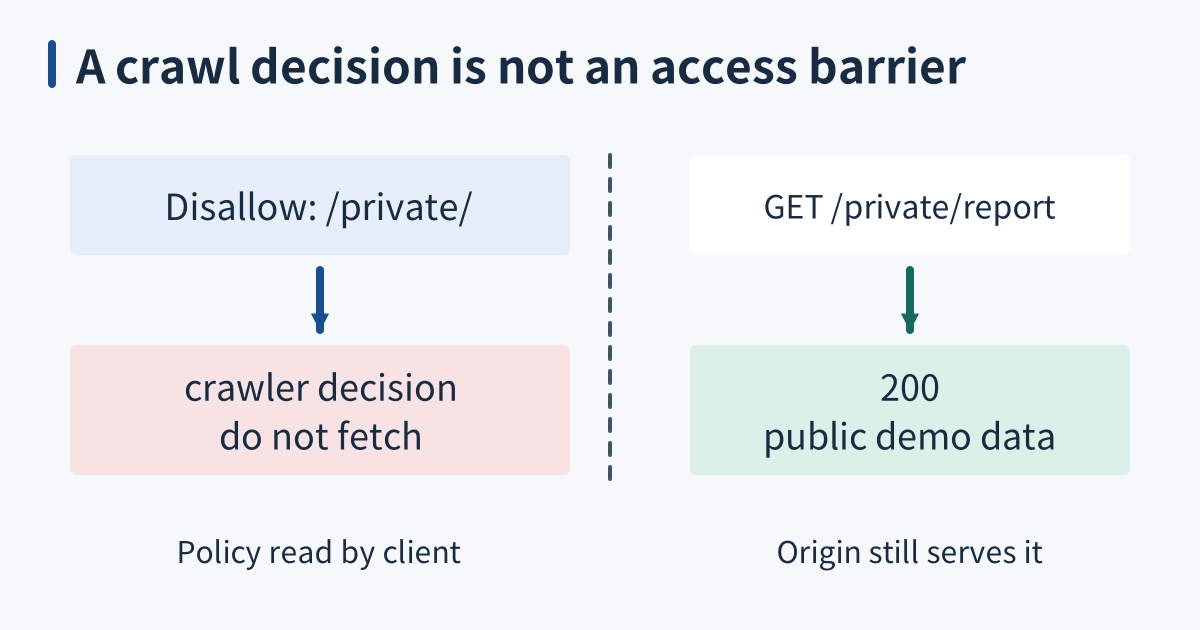
robots.txt guides crawlers but does not authorize access
A robots.txt file communicates crawling rules to automated clients that implement the Robots Exclusion Protocol. It can reduce unwanted traversal of expensive or unhelpful paths, but the server does not automatically enforce its contents against incoming requests. RFC 9309 explicitly separates these rules from access authorization. Treat robots.txt as a public interface for cooperating crawlers, while authentication and authorization decide who may actually retrieve protected resources. ...